OpenAI Models at Ultrafast Speed
OpenAI and Cerebras are partnering to bring the fastest inference to the mainstream.
See Ultrafast in action
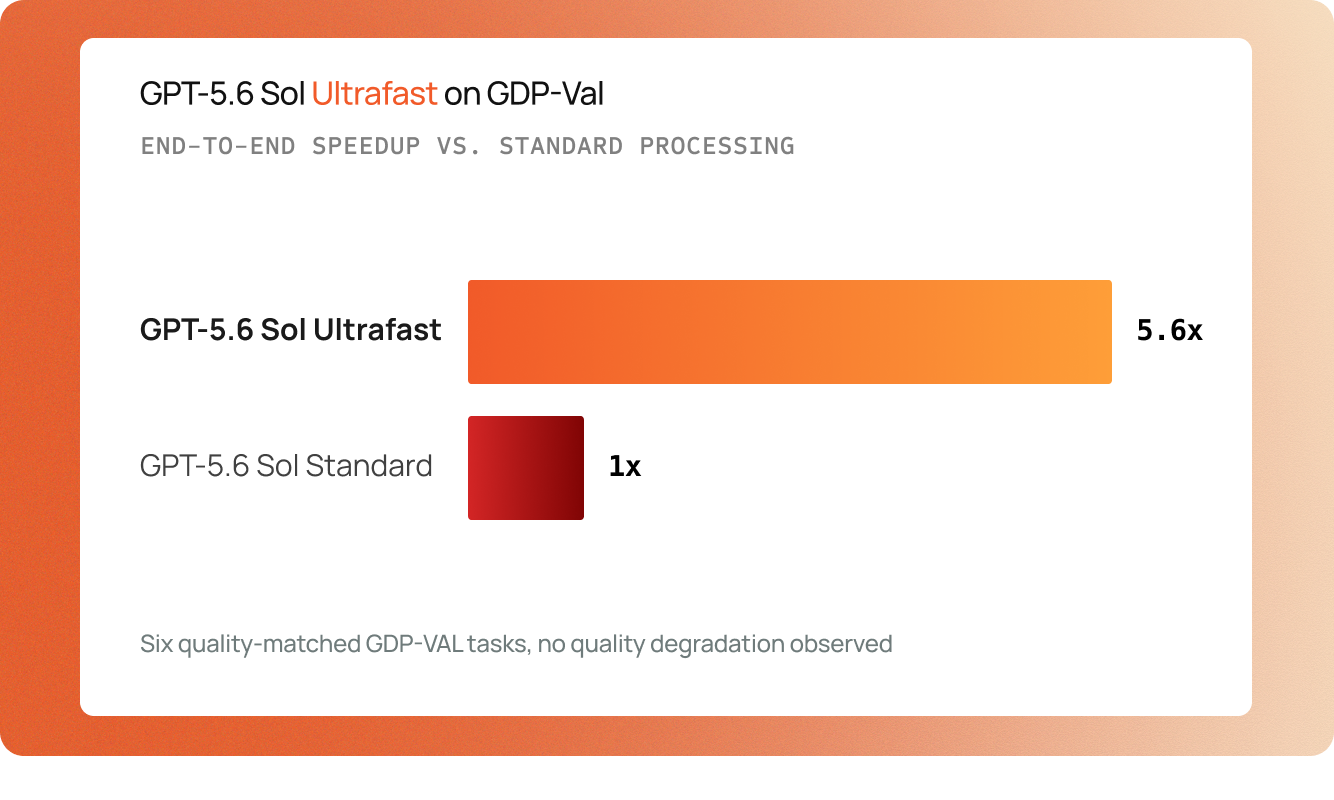
Explore four demos showing how Cerebras accelerates OpenAI models across demanding benchmarks, interactive applications, and complex workflows—bringing frontier intelligence to users at Ultrafast speed.
Up to 750
output tokens per second
Workhorse intelligence delivered at Ultrafast speed.
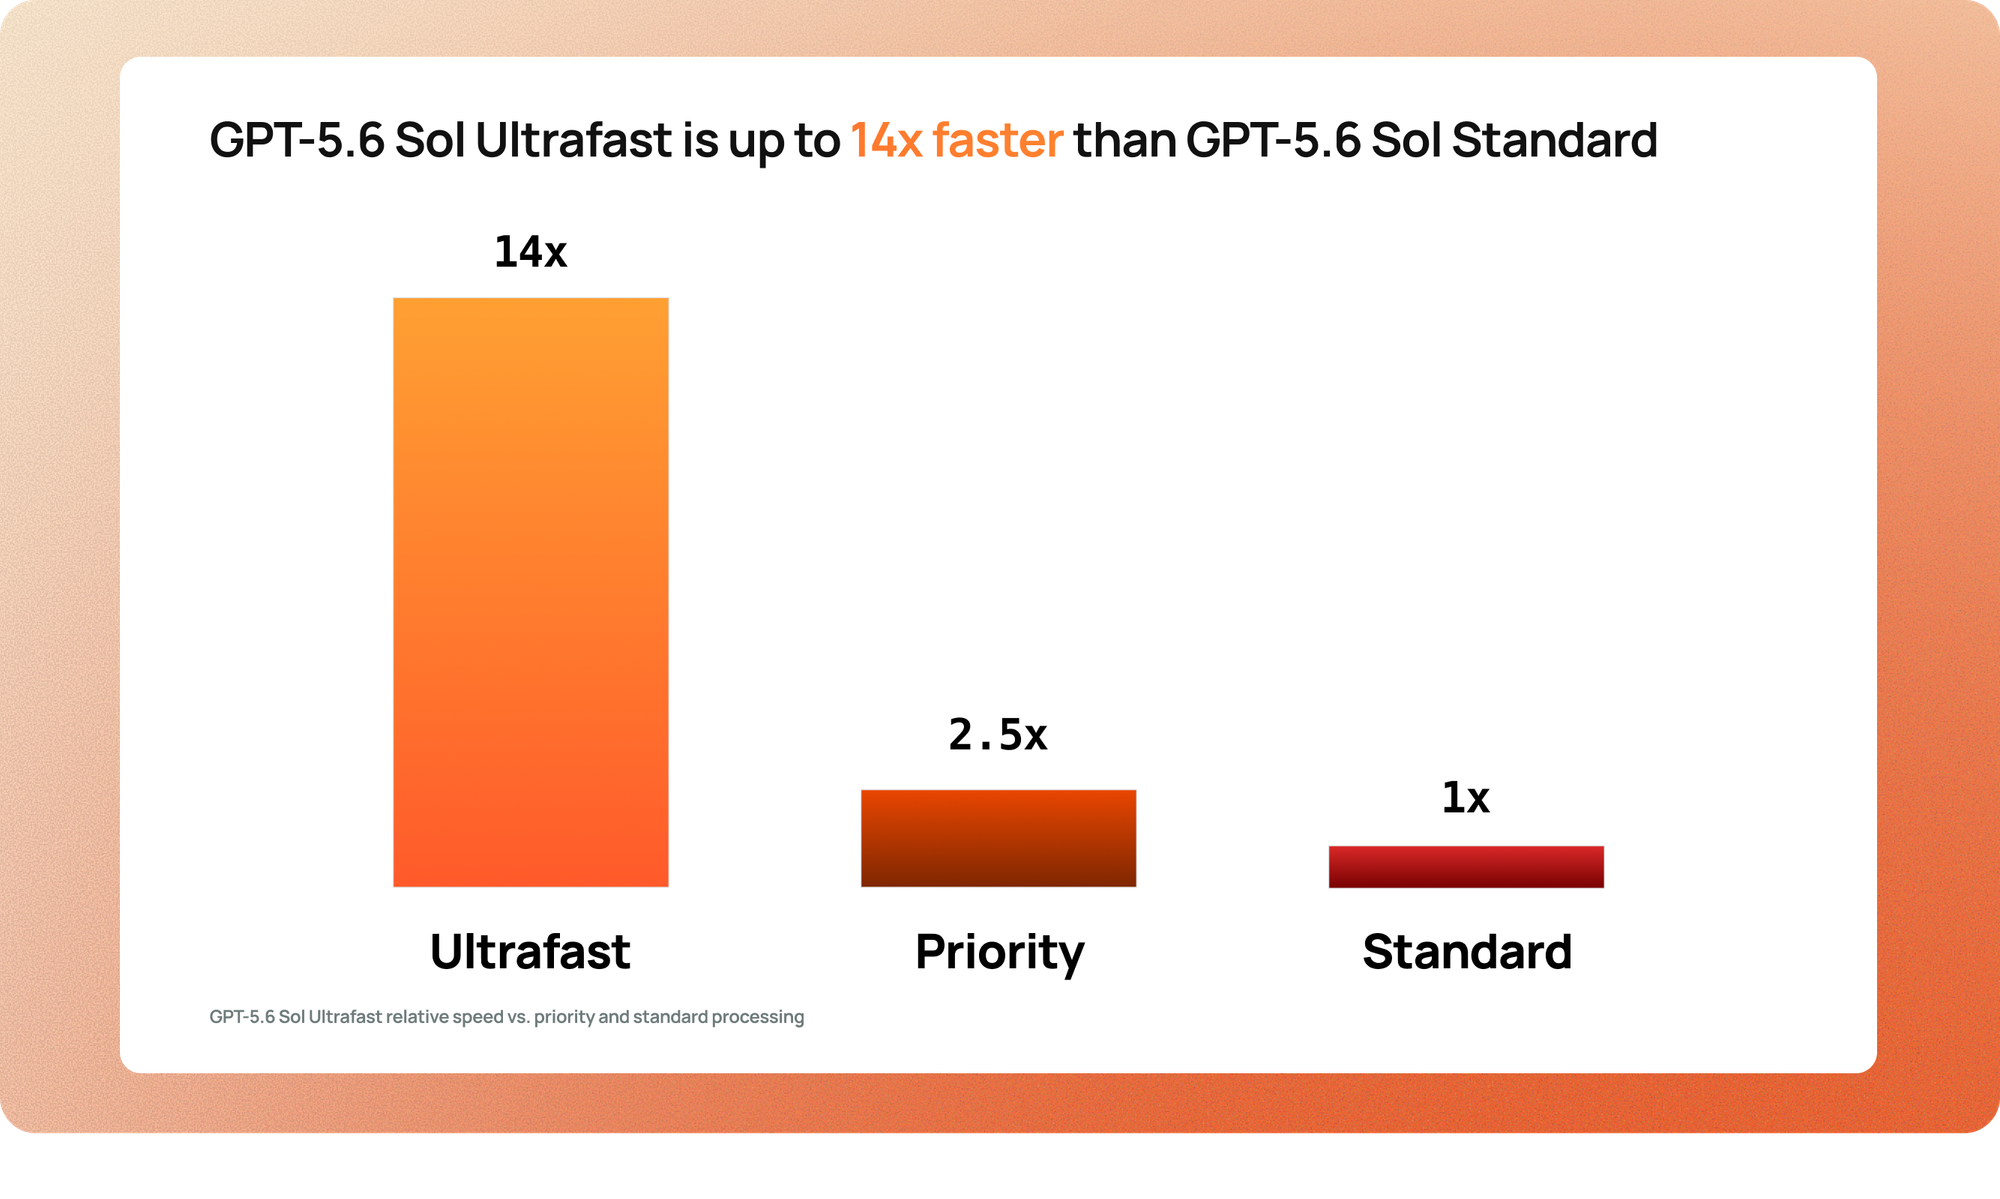
Up to 14×
faster than standard
A new speed class for GPT-5.6 Sol in the OpenAI API.
Faster intelligence
GPT-5.6 Sol intelligence
Lower latency without changing to a less capable model.
No more tradeoff between intelligence and speed
Ultrafast inference not only enables a better user experience, it also unlocks greater intelligence and more capable agents by doing more work per unit time.
Higher User Engagement
Ultrafast inference delivers real-time responses, keeping users engaged and in flow.
Higher Model Intelligence
Interactive applications don’t need to use a smaller, less intelligent model anymore.
More Powerful Agents
Do more reasoning and tool calling in the same time envelope, for even better outcomes.
Partnership progression
Real-time coding
GPT-5.3-Codex-Spark was the first release in the Cerebras and OpenAI collaboration, bringing a research-preview real-time coding model to ChatGPT Pro users through Codex at more than 1,000 tokens per second. GPT-5.6 Sol Ultrafast extends the collaboration to OpenAI's most capable model, delivering up to 750 output tokens per second in limited preview.
GPT-5.3-Codex-Spark
First release in the collaboration. Available in research preview to ChatGPT Pro users through Codex and served on Cerebras at more than 1,000 tokens per second.
GPT-5.6 Sol Ultrafast
OpenAI's most capable model on a new Ultrafast service tier, powered by Cerebras at up to 750 output tokens per second.
With GPT-5.6 Sol Ultrafast, Cerebras enables AI that keeps up with how you think, code, and collaborate. We’re excited to see how workflows and applications are transformed by Ultrafast inference.
Whereas formerly I might have to wait a couple minutes for a task to finish, it now finishes for me before I even have the opportunity to context-switch. It makes me way more productive.